- The tested group assigned DeepSeek to model-news research alongside other specialist agents.
- The report describes handoffs and QA revisions; it does not establish autonomous operation of an entire company or independently verified efficiency gains.
From research assignment to a shared briefing
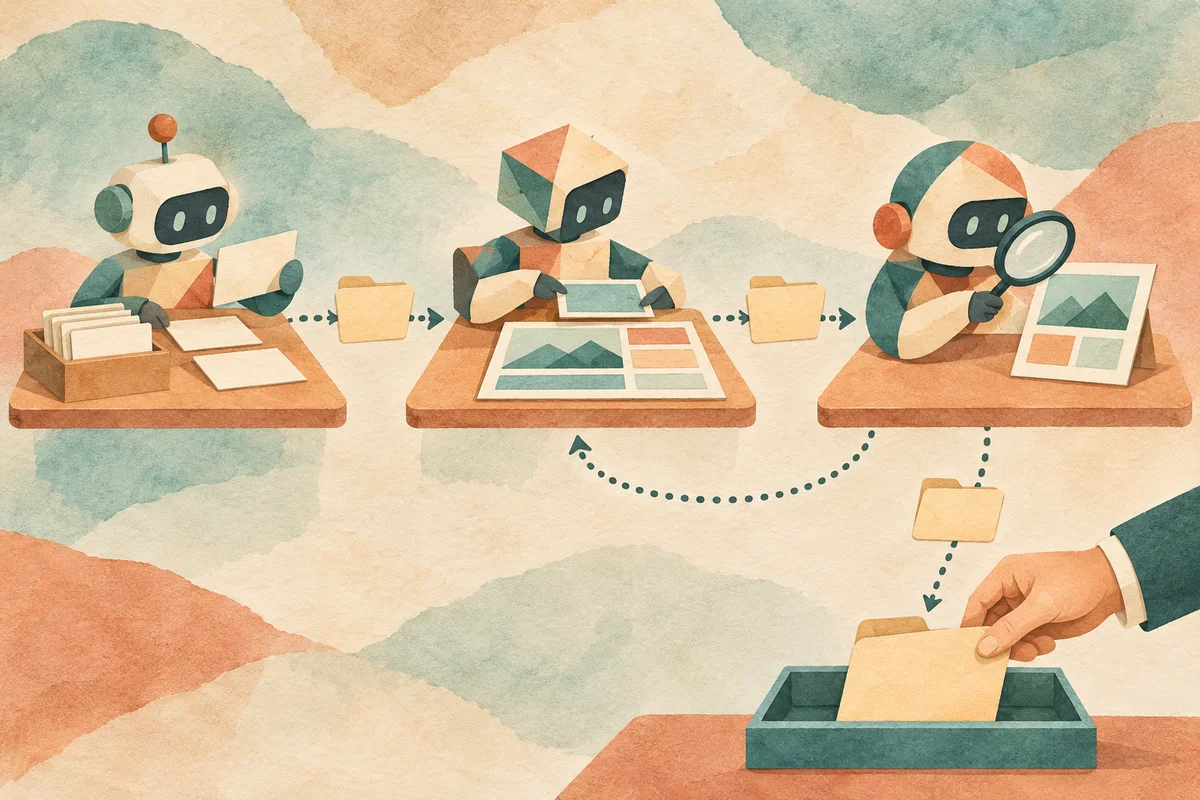
A November 9 QbitAI hands-on report describes testing LobeHub with an editorial agent group. The reporter assigned DeepSeek to model-news research alongside separate workers covering open-source projects and company personnel, coordinated by a supervising agent.
The group returned a six-item briefing, according to the account. The supervisor checked source quality and flagged unclear sourcing for rework subject to the user’s approval. The report says the deliverable also included worker receipts identifying details that needed human verification.
Reusing work without treating it as final approval
For a second task, the reporter asked the system to turn the existing briefing into a searchable webpage without gathering replacement material. The supervising agent created development and QA workers that reused the earlier output. QA identified two problems, which the developer then revised, the account says.
The article attributes that continuity to a shared workspace containing goals, progress, deliverables and acceptance records. It describes human acceptance as a continuing part of the workflow. These are one outlet’s task observations, not an independent audit of general reliability, productivity or companywide autonomy.
Sources & context
Go to the original material. Company claims remain attributed to their sources.
01