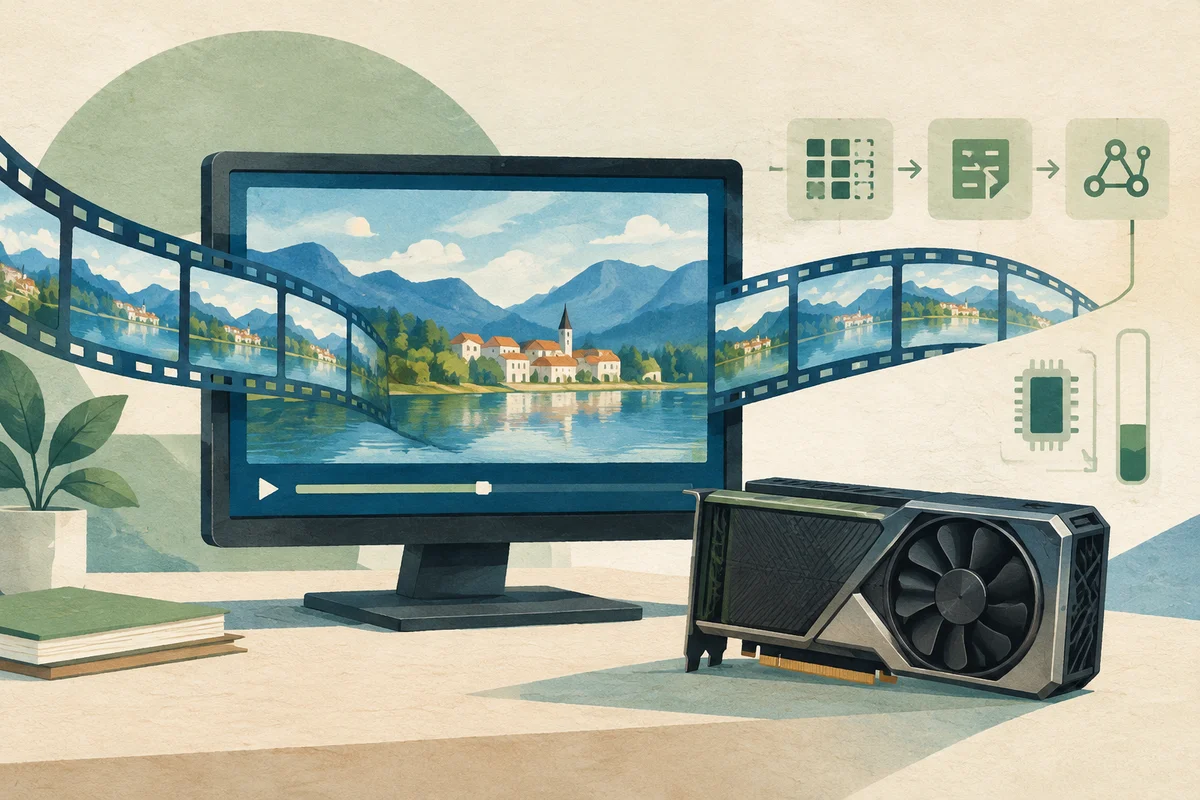
- MiniMax H3 can generate 15 seconds of video in 15 seconds or less on a single RTX 5090 with 32GB VRAM at 448×256 resolution.
- Optimizations including sparse attention, INT8 quantization and a fused FP4 MLP cut VRAM requirements from 80GB to under 30GB.
- The workflow uses FastVideo's FastH3 V2 checkpoint with four sampling steps and replaces H3's 32B text encoder with a 4B alternative to save memory.
- The open-source ComfyStreamerH3 node makes the optimized pipeline publicly available, lowering the barrier to experimenting with Chinese AI video models.
Real-Time Video on Consumer Hardware
ComfyUI developer Bryan Wade has published a technical demonstration showing that MiniMax H3, a video generation model from Shanghai-based Chinese AI company MiniMax (稀宇科技), can generate live video at real-time speed on a single NVIDIA RTX 5090 consumer GPU. The workflow produces 15 seconds of video in 15 seconds or less at 448×256 resolution, a milestone for running Chinese AI video models outside expensive cloud environments.
Running comparable video models continuously can cost upwards of $6,000 per day according to the post, making them impractical for individual developers and small teams. By targeting a GPU that can be rented for roughly 70 cents an hour, the project aims to bring Chinese AI video generation within reach of ordinary users.
Stacking Optimizations to Fit 32GB VRAM
The optimization stack combines several techniques to reduce VRAM usage from approximately 80GB to under 30GB. These include sparse attention that focuses computation on 20% of video blocks while skipping the rest, a pruned INT8 checkpoint from FastVideo, and a fused FP4 MLP that uses four-bit arithmetic to shrink weights and reduce memory transfers.
The workflow also replaces H3's default 32-billion-parameter text encoder with NicoLab28's ClipProj adapter based on Qwen3-VL-4B, cutting encoder memory from 15.7GB to about 4.5GB. Overlapping video decoding and NVENC encoding further improves throughput by keeping only the last frame between jobs instead of caching every decoded frame.
The system uses FastVideo's FastH3 V2 checkpoint with just four sampling steps. For comparison, FastVideo's earlier Preview V1 required 47.2 seconds on a far more expensive B200 GPU to generate a higher-resolution clip.
Open-Source Release and Next Steps
The optimized pipeline has been released as an open-source ComfyUI node called ComfyStreamerH3. Wade acknowledges that the output has visible artifacts and rough edges at this resolution, but suggests pairing the fast low-resolution generation with cost-efficient upscaling models as a practical next step.
The demonstration highlights how community-driven engineering can extend the practical deployment of Chinese AI video models beyond their original cloud-oriented designs, potentially accelerating experimentation and adoption among independent developers.
Sources & context
Go to the original material. Company claims remain attributed to their sources.
01