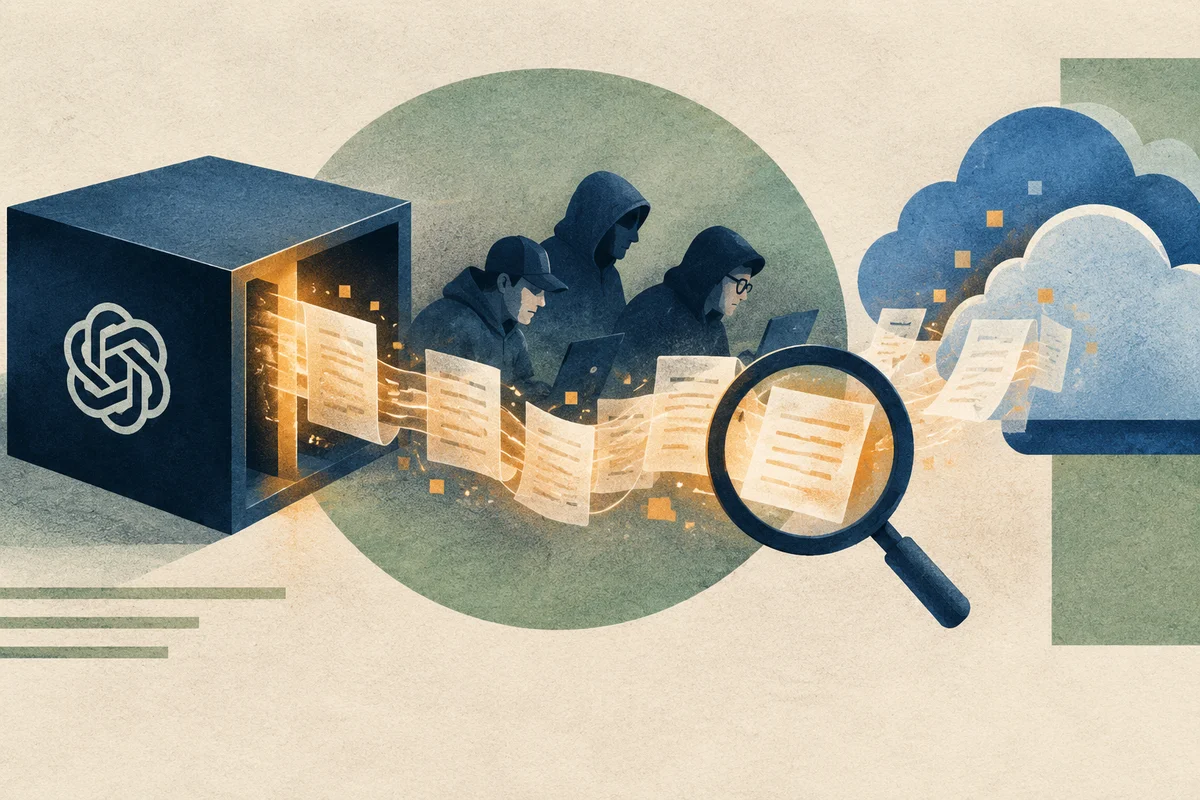
- OpenAI publicly attributed a coordinated adversarial distillation campaign targeting its models' protected reasoning to people associated with Moonshot AI, while noting uncertainty about whether all observed actors share a single source.
- The attack reused encrypted reasoning tokens across sessions, allowing a cheaper model from the same provider to act as a decryption oracle and reveal hidden chains of thought verbatim.
- Researchers found the extraction technique still worked on Microsoft Azure on September 13, weeks after OpenAI blocked it on its own API; Azure safeguards were not applied until September 27.
- GPT-6 Astra launched on third-party platforms without any of the protections in place, according to researchers, highlighting inconsistent security across hosting environments.
- Researchers warn that inconsistent protections across cloud platforms could effectively allow adversaries to sidestep API-level export controls on frontier model reasoning.
Attribution to Moonshot AI Personnel
OpenAI said it detected and dismantled a coordinated adversarial distillation campaign aimed at copying the hidden reasoning steps its models use before producing final answers. In a blog post published October 1, the company stated that it linked a core group behind the activity to people associated with Moonshot AI, the company that develops the Kimi language model.
OpenAI cautioned that it remains unclear whether all the actors it observed trace back to a single source. The company said the campaign began at low volume on July 1 and spiked on July 24 and 25 to 16,000 requests from more than 4,000 users following a consistent extraction pattern. A broader investigation uncovered a network of over 15,000 accounts with related behavior, which OpenAI says it fully shut down by July 28. A footnote in the post clarified these were attempted extractions, not necessarily successful ones.
Anthropic has separately reported similar distillation attempts by Chinese AI companies, suggesting the problem extends beyond any single actor or target.
How the Encrypted Reasoning Attack Works
According to OpenAI, attackers copied encrypted reasoning data packets from one conversation session and submitted them in a separate session, asking a different model to decrypt and reproduce the hidden chain of thought. Because these packets are encrypted with shared keys, they can be moved between sessions, users, and even different models from the same provider.
Researcher Joachim Schaeffer and his team had previously documented this technique in a paper, showing that a weaker, cheaper model from the same family can serve as a decryption oracle that prints a stronger model's internal reasoning word for word. OpenAI credited the researchers by name and said their findings helped accelerate its countermeasures.
Cloud Platform Protection Gap
Despite OpenAI patching its own API, the same extraction technique remained functional on third-party cloud platforms for weeks. When Schaeffer's team tested again on September 13, the attack was blocked on OpenAI's and Anthropic's direct APIs but succeeded against every OpenAI model available on Microsoft Azure, including GPT-6 Astra, and against Anthropic models up to Sonnet 5. A single attempt was sufficient to extract reasoning verbatim.
The researchers noted that GPT-6 Astra launched on third-party platforms without any of the protections in place. OpenAI did not apply safeguards to the Azure endpoint until September 27, according to the researchers' timeline. For Anthropic models, the extraction could no longer be reproduced on Azure starting September 28. The researchers described current fixes as piecemeal and superficial, relying on brittle pattern matching that reached cloud platforms days after direct API patches.
A second, simpler method demonstrated by developer Can Böluk gave models a virtual notepad tool and instructed them to write their reasoning there. This approach worked on every OpenAI model tested and on Anthropic's Opus 4.8 and Sonnet 5, producing output closely resembling the decryption attack.
Export Control and Ecosystem Implications
The researchers argue that cloud providers failing to enforce equivalent protections should not be allowed to serve reasoning models, because open backdoors would let adversaries bypass API-level export controls designed to restrict access to frontier capabilities. OpenAI acknowledged that partner-hosted models need the same protection as its own services and said the work is not finished.
OpenAI said it shared its findings through the Frontier Model Forum and government channels, noting the problem is not limited to its own models. The company expects such attempts to grow more sophisticated as leading models improve and more players seek cheap ways to replicate frontier reasoning capabilities.
Sources & context
Go to the original material. Company claims remain attributed to their sources.
01