- MiDashengLM-Spatial is the latest entry in Xiaomi's open-source audio AI lineage, following the Dasheng audio encoder and MiDashengLM-7B model.
- The model uses a hierarchical semantic-to-spatial conditioning module to integrate spatial awareness without sacrificing general audio understanding capabilities.
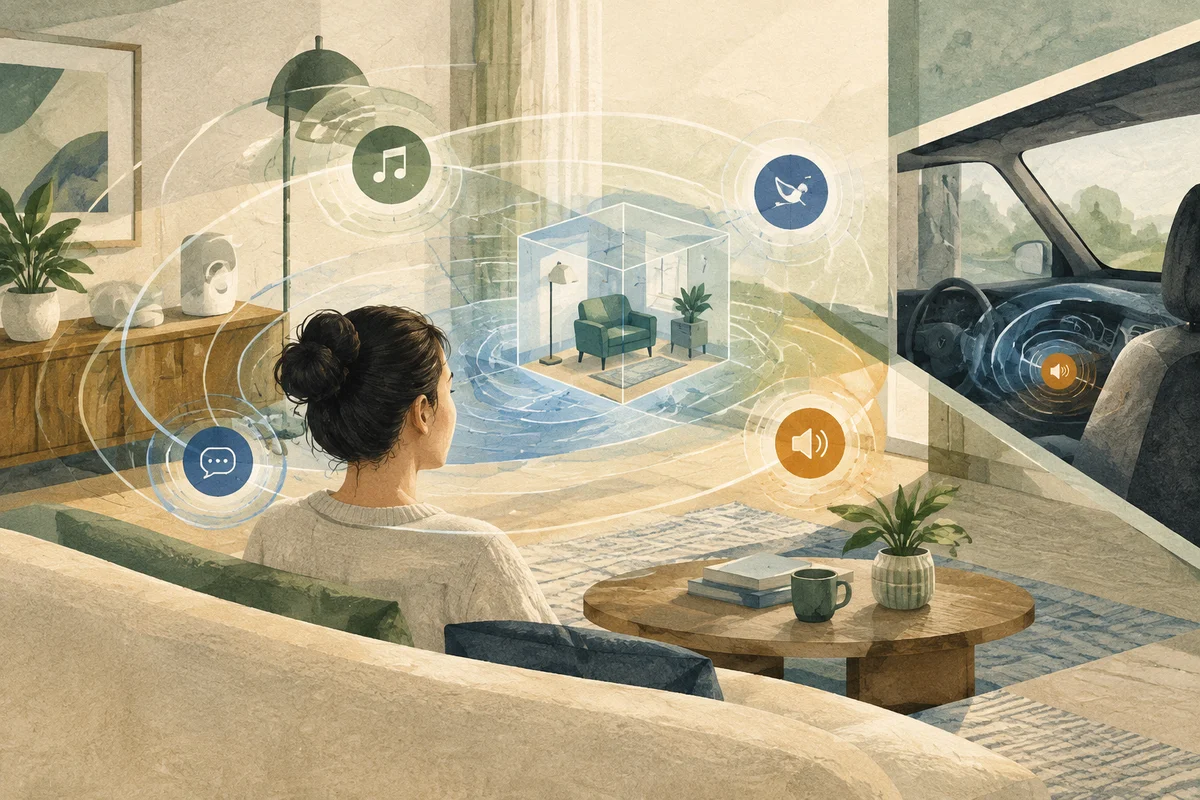
- Xiaomi plans to deploy the model in smart home and car cockpit scenarios to enhance spatial interaction within its human-car-home ecosystem.
- Full model weights, inference code and a project demo are publicly available under the permissive Apache 2.0 license.
Spatial Audio Model Release
Xiaomi has open-sourced MiDashengLM-Spatial, an audio-language model that combines general audio understanding with spatial awareness in a single architecture. The company describes it as the industry's first open-source end-to-end spatial audio understanding large model. Full model weights and inference code are released under the Apache 2.0 license, permitting both research and commercial use.
The model extends Xiaomi's existing MiDashengLM-7B by integrating a dedicated spatial audio encoder called Spatial-Dasheng. A hierarchical semantic-to-spatial conditioning (HSSC) module conveys intermediate semantic representations to corresponding layers of the spatial branch, allowing the model to leverage semantic context while maintaining functional separation between the two processing streams. According to the project documentation, this design enables binaural perception and spatial audio understanding while preserving the base model's general audio capabilities.
Training Data and Ecosystem Applications
The project team constructed a scalable spatial-scene synthesis pipeline comprising approximately one million spatial acoustic scenes totaling around 13,000 hours of environmental sounds, speech and music, along with six million fact-verified question-answer pairs. Experiments cited in the accompanying arXiv preprint indicate that Spatial-Dasheng delivers robust spatial perception and sim-to-real generalization without compromising general audio understanding performance.
Xiaomi stated that MiDashengLM-Spatial will be applied in smart home and car cockpit scenarios to improve spatial interaction within its human-car-home ecosystem. Over the past two years, the company's prior audio models — the Dasheng encoder and MiDashengLM-7B — have been deployed in more than 30 applications across these domains, supporting unified perception of speech, environmental sounds and music. The new spatial capabilities aim to enable the model not only to recognize sound content but also to determine sound sources and their spatial distribution.
Sources & context
Go to the original material. Company claims remain attributed to their sources.
01