- Tool-call repetition emerged as a significant user-experience issue after the MiMo-V2.6 release, with exact within-turn repetition rates exceeding 0.05% across agent harnesses.
- Xiaomi traced the problem to RL training dynamics: a per-turn flooding penalty threshold of 32 tool calls was too permissive, allowing sub-threshold flooding behavior to amplify over successive training steps.
- A stricter threshold reduced repetition but did not eliminate it and would have cost an estimated $2.31 million to apply at full scale.
- The adopted MOPD approach used a specialized single-turn RL teacher trained on approximately 7,000 repetition examples, reducing replay repetition to zero at a total training cost of about $90,000.
- Updated MiMo-V2.6-Pro and MiMo-V2.6-Flash checkpoints with the MOPD fix have been available via Xiaomi's API since September 25, and all MiMo Desktop users received a quota reset.
Repetition as a Post-Launch Failure Mode
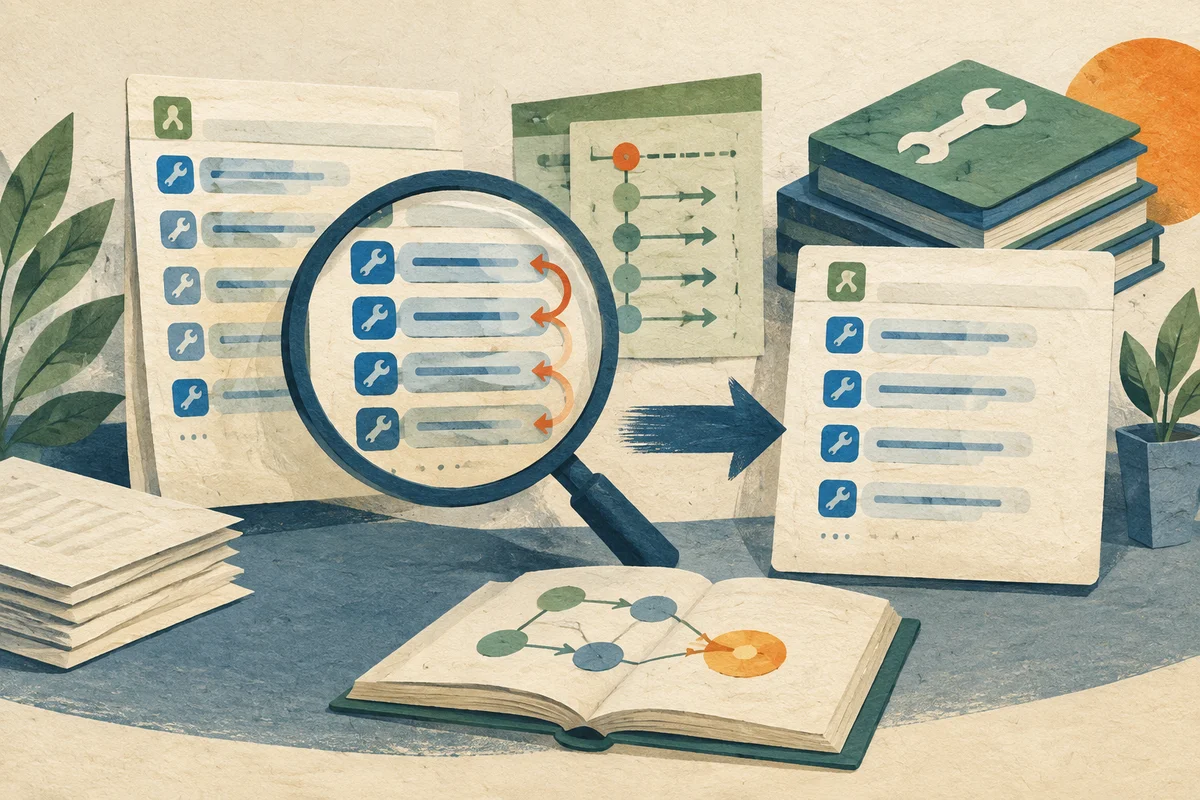
Following the release of MiMo-V2.6, Xiaomi identified tool-call repetition as one of the most noticeable issues affecting users of MiMo Desktop, MiMo Code and other agentic environments. The model would sometimes issue identical or highly similar tool calls repeatedly without making progress, consuming substantial time and context window capacity.
Internal evaluations confirmed response-level repetition rates exceeding 0.05%, with the OpenCode harness showing the highest rates at 1.02% for MiMo-V2.6-Flash-RL and 0.54% for MiMo-V2.6-Pro-RL. Xiaomi distinguished this behavior from legitimate parallel tool calling and from tool-call flooding, defining repetition as repeated actions with no reasonable justification when neither available information nor environment state has materially changed.
Tracing the Problem to RL Training Dynamics
By replaying fixed internal examples against checkpoints from different RL training stages, Xiaomi found that the share of examples exhibiting flooding—more than ten tool calls in a single turn—rose from 11.1% at RL step 0 to 24.6% by step 20. Under the MiMo Code harness specifically, the flooding share grew from 30.6% to 41.7%.
The existing RL pipeline included a flooding penalty that set reward to zero when a single turn exceeded 32 tool calls, but analysis of training traces showed this threshold was too permissive. Behavior below the threshold was not penalized and was gradually amplified during training until it crossed into severe flooding.
Reward-Design Tradeoffs and the Costly Threshold Fix
Xiaomi experimented with lowering the flooding-penalty threshold from 32 to eight calls per turn, resuming training from the step-28 checkpoint. The stricter penalty suppressed flooding effectively, but the improvement required approximately 20 additional training steps to emerge. Applying this fix at full scale would have meant restarting 20 steps of MixRL training at an estimated cost of $2.31 million.
Even after this costly intervention, replay testing showed the repetition rate fell from 13.45% to 3.83% but was not eliminated, and the fix generalized poorly to evaluation sets with longer conversation histories where repetition rates remained above 16%.
MOPD as a More Efficient Alternative
Xiaomi ultimately adopted Multi-teacher On-Policy Distillation (MOPD). The team first trained a specialized single-turn RL teacher using internally collected repetition examples, assigning a reward of 0 when repetition occurred and 1 only when a rollout contained neither repetition nor erroneous tool use. After just 12 training steps comprising approximately 7,000 examples, this teacher reduced replay repetition to zero on both training and held-out sets.
The MOPD run rolled back five steps from the final checkpoint, introduced the repetition-specialized teacher, and continued training with teacher-prefix on-policy distillation. The company reported that the complete MOPD training run cost approximately $90,000, which it described as only 4% of the estimated cost of the MixRL threshold-lowering alternative. After MOPD, repetition rates for both Pro and Flash variants dropped substantially across context lengths and agent harnesses while broader benchmark performance held steady.
Updated Models Released
Xiaomi open-sourced the updated MOPD checkpoints in the MiMo-V2.6 collection on Hugging Face, with model names carrying the MOPD suffix. The updated models have been available on Xiaomi's API platform since September 25 at 06:00 Beijing time under the unchanged model names mimo-v2.6-pro and mimo-v2.6-flash.
As compensation for the disruption, Xiaomi announced it will reset the remaining quota in the current usage window for all MiMo Desktop users.
Sources & context
Go to the original material. Company claims remain attributed to their sources.
01